T1#ethics#research
The Asilomar AI Principles — Writing AI Safety Down in 23 Points
Metadata
- Date
- Decade
- 2010s
- Tier
- T1
- Sources
- 08
- Connections
- 06
- Tags
- #ethics#research
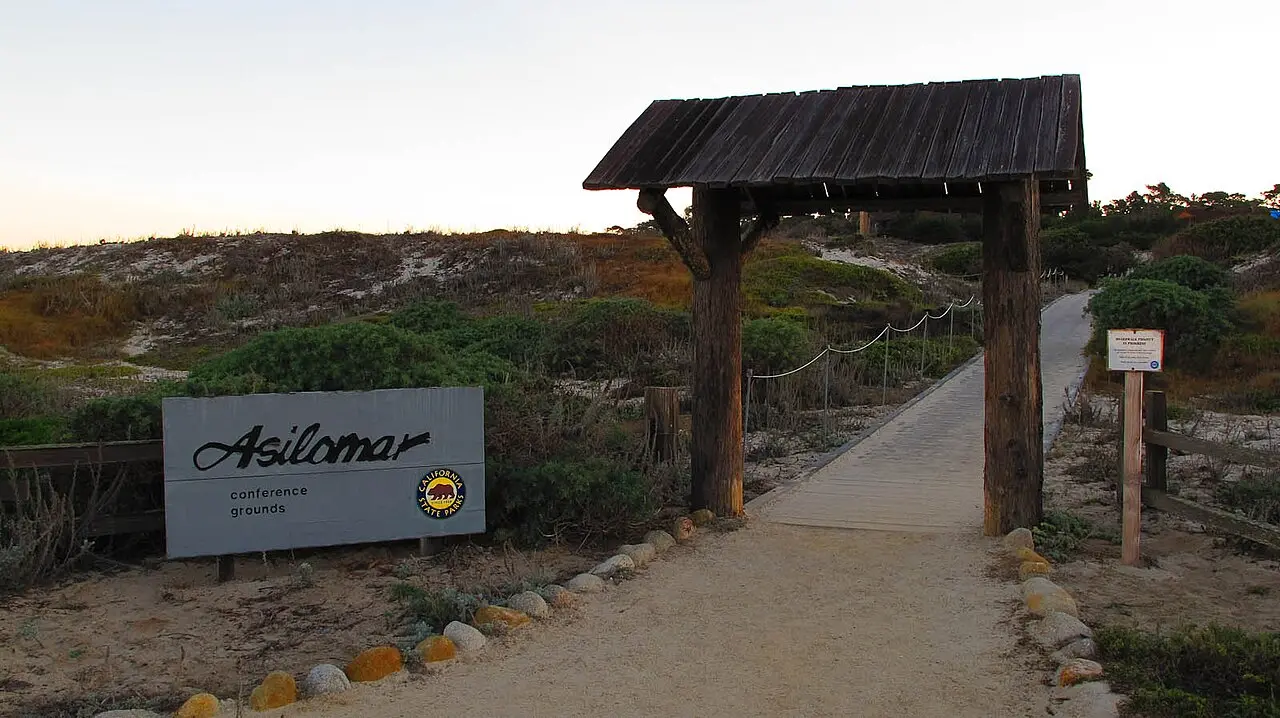
AI safety is the umbrella term for research and practice aimed at keeping AI systems from causing harm their makers did not intend. The 2016 paper "Concrete Problems in AI Safety" called the core problem "accidents" and defined them as "unintended and harmful behavior that may emerge from poor design of real-world AI systems." An early example of researchers, executives, economists and lawyers writing that concern down in a single document is Beneficial AI 2017, a conference held at Asilomar, California, from 5 to 8 January 2017, and the 23 Asilomar AI Principles that came out of it.
According to the organiser, the Future of Life Institute (FLI), every one of the 23 principles was kept only because at least 90% of conference participants supported it. They carry no legal force. Even so, the issues that recur throughout later AI policy — safety, value alignment, not cutting corners on safety in a race, planning for catastrophic risk — appear here side by side in one text.
What "AI safety" refers to
The phrase covers different ground for different people. Two widely used framings:
| Source | Definition or scope |
|---|---|
| Amodei et al., "Concrete Problems in AI Safety" (June 2016) | "Accidents" in machine-learning systems — unintended, harmful behaviour from poor design. Five problems: avoiding side effects, avoiding reward hacking, scalable supervision, safe exploration, distributional shift |
| Asilomar Principle 6, "Safety" (January 2017) | AI systems should be safe and secure throughout their operational lifetime, and verifiably so where applicable and feasible |
The first deals with design flaws in systems running today; the second states a requirement for a system's whole working life. The Asilomar text goes further: Principle 10 asks that highly autonomous AI be designed so its goals and behaviour can be assured to align with human values — what is now called alignment — and Principle 21 asks that catastrophic or existential risks be met with planning and mitigation commensurate with their expected impact. Today's "AI safety" debate uses one phrase for everything from near-term accident prevention to the control of future advanced AI, and that breadth is already visible in this document.
Beneficial AI 2017
FLI's record shows a grant-recipient workshop on 3–5 January 2017 followed by the conference on 5–8 January. It was billed as the follow-up to the AI conference FLI had held in Puerto Rico in 2015.
Speakers included Max Tegmark, Erik Brynjolfsson, Yoshua Bengio, Stuart Russell, Daniel Kahneman, Demis Hassabis, Ray Kurzweil, Yann LeCun and Nick Bostrom. Panellists included Elon Musk, Sam Altman, Eric Schmidt, Andrew Ng, Kate Crawford and Dario Amodei. AI researchers from academia and industry sat alongside specialists in economics, law, ethics and philosophy.
How the 23 were chosen
FLI describes the process this way. The team read existing reports on AI's opportunities and threats and compiled a long list of views on how the technology should be managed. It distilled the overlaps into draft principles and asked attendees in advance for improvements and additions. At the conference, small breakout groups debated the draft, producing new principles, improved versions and, in several cases, competing wordings of a single principle. A final survey of all attendees measured support for each version, and only those with at least 90% support were kept.
| Section | Principles | Main content |
|---|---|---|
| Research Issues | 1–5 | Beneficial rather than undirected intelligence; funding for research on beneficial use; exchange between researchers and policy-makers; a culture of cooperation and transparency; cooperation to avoid corner-cutting on safety (race avoidance) |
| Ethics and Values | 6–18 | Safety; failure transparency; judicial transparency; designer responsibility; value alignment; human values; personal privacy; shared benefit and prosperity; human control; non-subversion of civic processes; avoiding an arms race in lethal autonomous weapons |
| Longer-term Issues | 19–23 | No strong assumptions about upper limits on capability; care proportionate to a profound change in the history of life on Earth; planning for catastrophic and existential risks; strict controls on recursive self-improvement; superintelligence only for the benefit of all humanity |
Principle 1 reads: "The goal of AI research should be to create not undirected intelligence, but beneficial intelligence." Principle 23 says superintelligence should be developed only in the service of widely shared ethical ideals and for the benefit of all humanity rather than one state or organisation.
Signatures and support
After publication the principles became an open letter collecting signatures. Viewed on 18 October 2026, FLI's page lists 1,200 AI and robotics researchers and 2,342 others (the counter at the top shows 5,720). An Inverse article of 2 February 2017 reported 892 AI or robotics researchers and 1,445 other experts, including Elon Musk and the physicist Stephen Hawking, and noted that the list was not comprehensive and was open to differing interpretations.
The voices FLI collected from attendees differed in tone. Anca Dragan of UC Berkeley said robots would not try to revolt against humanity but would simply try to optimise whatever they were told to do — moving the alignment problem away from the rebellion story.
What it changed
How much can a non-binding list of principles do? That is where assessments of the document divide.
On the policy side, the California Legislature unanimously adopted ACR 215 on 30 August 2018, supporting the 23 principles as guiding values for AI development and related policy; Assemblyman Kevin Kiley led the effort. FLI's own announcement stated plainly that the principles do not establish enforceable policies or regulations.
Internationally, AI safety became an intergovernmental agenda item six years later. The declaration of the AI Safety Summit at Bletchley Park on 1–2 November 2023 was joined by 28 countries — Japan, the United States and China among them — and the EU, which committed to cooperate on research into frontier AI safety. No document shows that the Asilomar text was its direct template, but the overlap in subject matter is large.
Other researchers have pointed to the limits of principle-writing itself. Jobin, Ienca and Vayena's 2019 analysis in Nature Machine Intelligence mapped AI ethics guidelines from companies, research institutions and public bodies and found global convergence on five principles — transparency, justice and fairness, non-maleficence, responsibility and privacy — but substantive divergence in how they are interpreted, why they matter, whom they cover and how they should be implemented. Agreeing on principles and having a mechanism to enforce them are different things.
Principle 5 (no corner-cutting in a race) and Principle 21 (planning for catastrophic risk) are often cited when later events are discussed. In March 2023 the same FLI published a letter calling for a six-month pause on training AI more powerful than GPT-4; that story and its reception are told in the AI pause letter.
Principle 2 asks that AI investment be accompanied by funding for research on beneficial use, and lists as examples robustness against malfunction and hacking, keeping people's resources and purpose amid automation, updating legal systems, and the values AI should be aligned with. By framing safety as a problem spanning engineering, economics, law and ethics, it reads much like a table of contents for today's debate on AI and society. But a non-binding agreement imposes no cost on anyone who ignores it, and the gap Jobin and colleagues found between convergent principles and divergent implementation applies to Asilomar as well.
Questions this page answers
- What is AI safety?
- It is the research and practice of keeping AI systems from behaving in unintended, harmful ways. The 2016 paper Concrete Problems in AI Safety defined the accidents at its core as unintended and harmful behaviour that may emerge from poor design of real-world AI systems.
- When and where were the Asilomar AI Principles written?
- At Beneficial AI 2017, a conference the Future of Life Institute held at Asilomar, California, from 5 to 8 January 2017. A draft distilled from views gathered beforehand was debated in breakout groups, and the 23 principles that won at least 90% support in a survey of all attendees were kept.
- Are the Asilomar AI Principles legally binding?
- No. FLI itself says the principles do not establish enforceable policies or regulations. The California Legislature did, however, unanimously adopt ACR 215, a resolution supporting them, on 30 August 2018.
- Who signed them?
- FLI's page lists 1,200 AI and robotics researchers and 2,342 others. Coverage in February 2017 reported that Elon Musk and the physicist Stephen Hawking were among the endorsers.
Sources
PrimaryAsilomar AI Principles — Future of Life Institute
Full text of the 23 principles, the three-part structure, their origin at Beneficial AI 2017, and signature counts (1,200 AI/robotics researchers, 2,342 others, counter at 5,720; viewed 18 October 2026)
PrimaryA Principled AI Discussion in Asilomar — Future of Life Institute, Jan 18, 2017
The drafting process from distilled views through breakout groups to the all-attendee survey, and the at-least-90% threshold
PrimaryBeneficial AI 2017 — Future of Life Institute
Dates (workshop 3–5 January, conference 5–8 January), its role as the follow-up to the 2015 Puerto Rico conference, speakers and panellists
The definition of accidents in machine-learning systems and the five research problems
PrimaryState of California Endorses Asilomar AI Principles — Future of Life Institute, Aug 31, 2018
Unanimous adoption of ACR 215 on 30 August 2018, Assemblyman Kevin Kiley, and the note that the principles are not enforceable
PrimaryThe Bletchley Declaration by Countries Attending the AI Safety Summit, 1-2 November 2023 — GOV.UK
28 countries and the EU, including Japan, the United States and China; New Zealand joined on 23 October 2024
The finding of convergence on five principles alongside substantive divergence in interpretation and implementation
SecondaryStephen Hawking and Elon Musk Endorse 23 Asilomar Principles for A.I. — Inverse, Feb 2, 2017
Early signature counts (892 AI/robotics researchers, 1,445 others) and the endorsement by Musk and Hawking
Last updated: